Data Labelling Services
What is a data labelling service?
Data labelling is the process, wherein a data set obtained from a raw form is labeled so as to be comprehensible to the machine learning algorithms. It is a very important process of AI training because it gives models all the information, they need to learn patterns and make decisions.
Infosearch is a leading data labelling company providing high quality AI data labelling and annotation services to our clients in 35+ countries throughout the world. We train our annotators on specific labelling tasks for machine learning and model building.

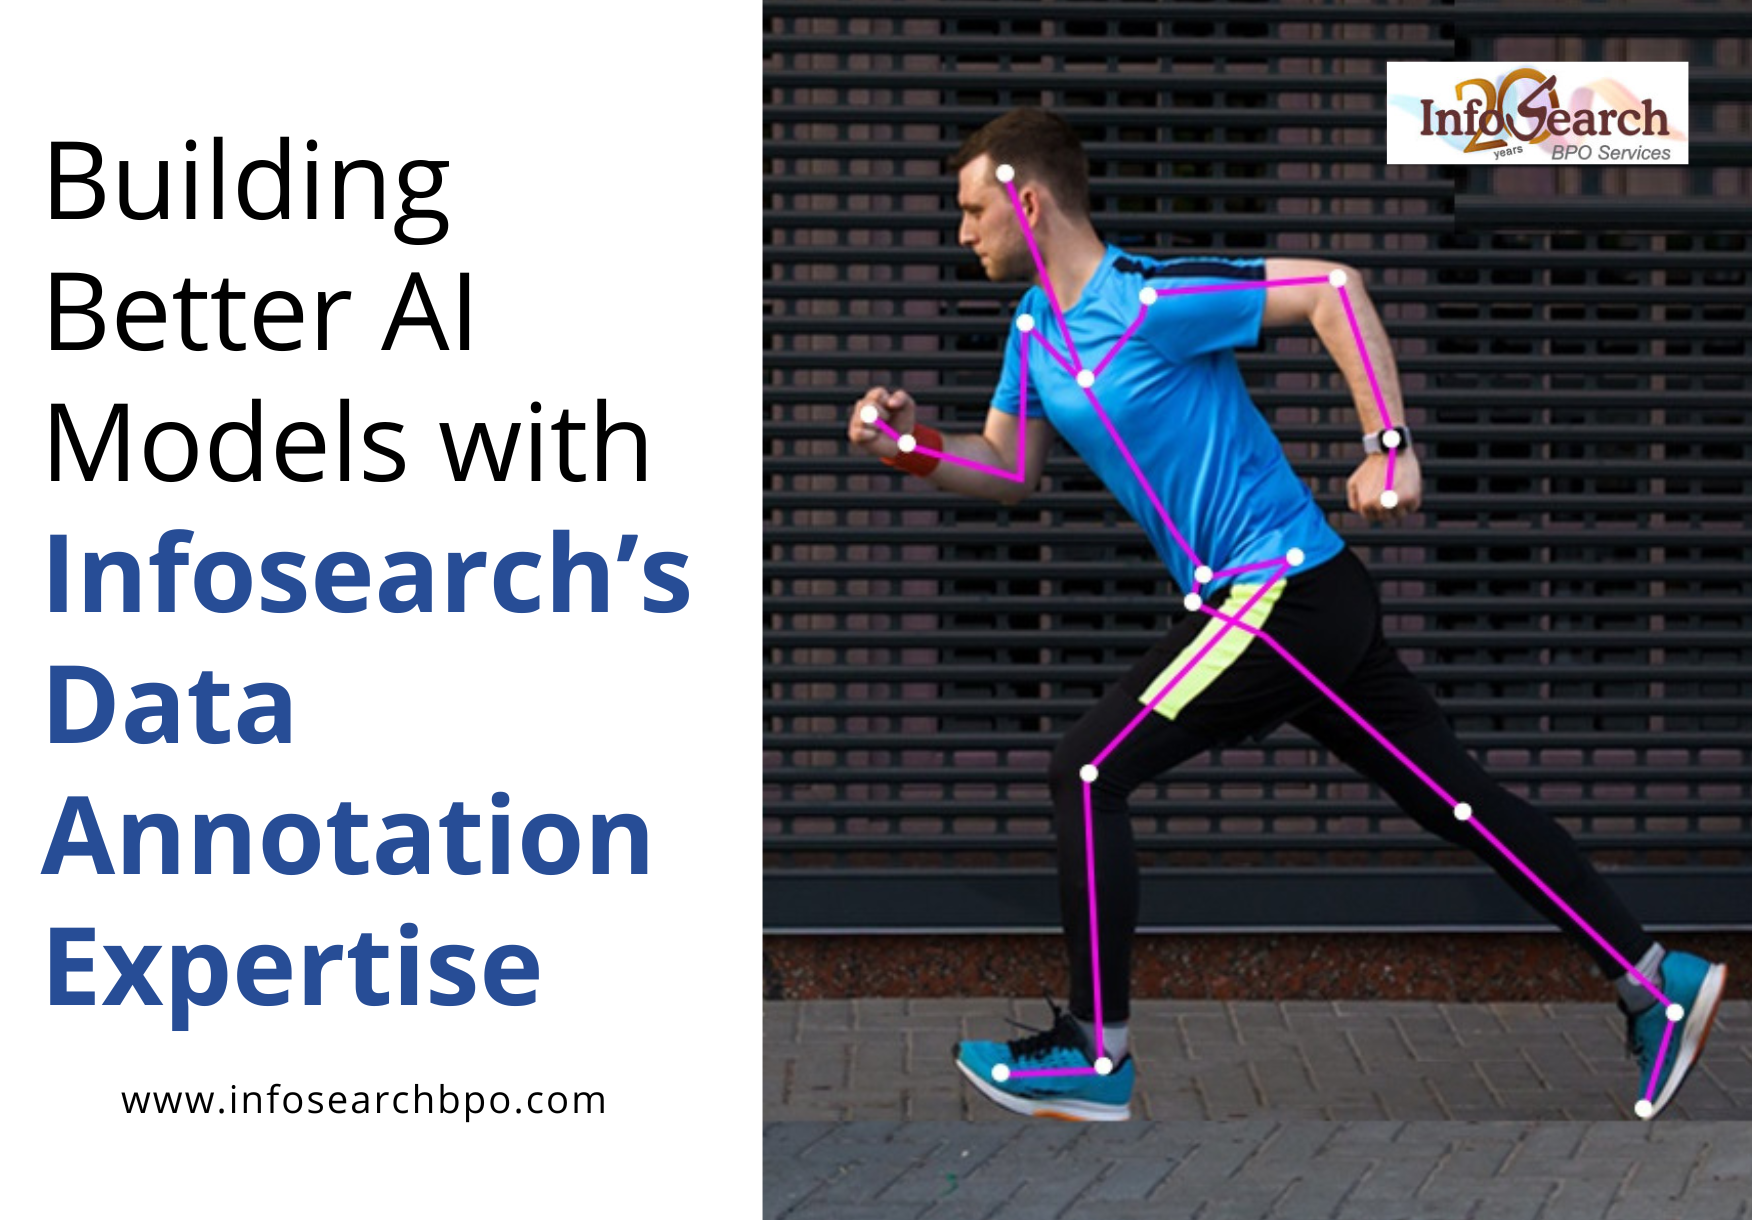
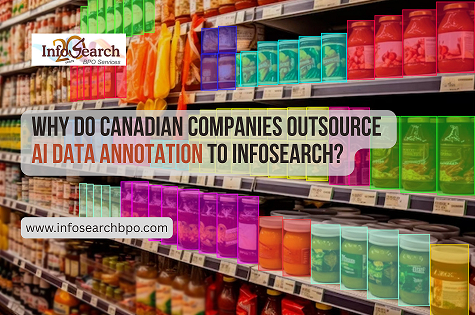
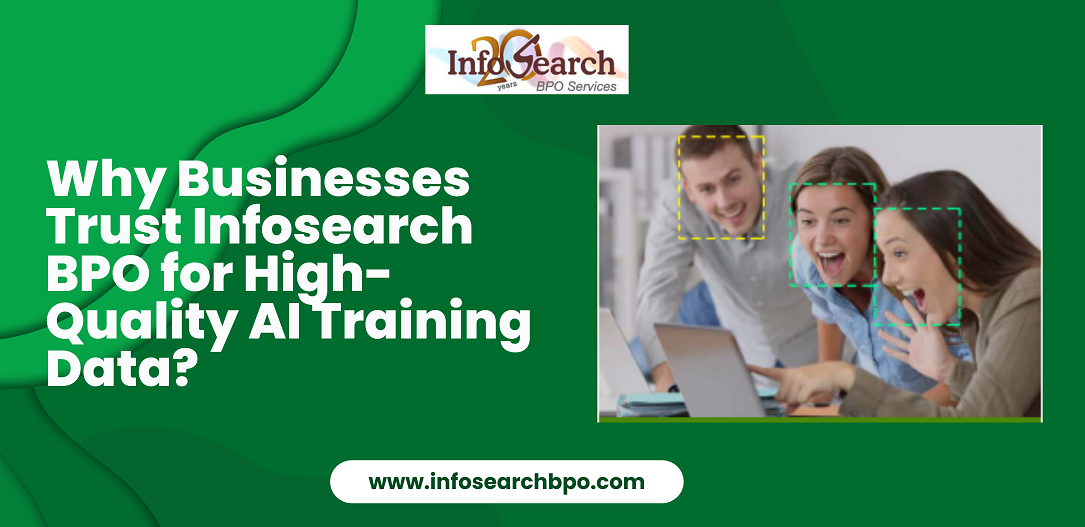
Image Labelling

3D Cuboid Labelling

Logo and Brand Labelling
Common Types of Data Labelling Services Provided at Infosearch Are:
Image labelling
Operation of labelling objects, people or actions depicted in the images.Text labelling
They include classification, annotation or text mining, which entails putting the contents of the text into some sort of category or tag, or extracting data from the text.Audio labelling
Transcribing speech or identifying speakers or classifying the audio content of a particular video or pod cast.Video labelling
The area is concerned with recognizing objects, actions, or events on frames within the video.The Data Labelling and Annotation Process Typically Involves:
- Data collection: Assembling the data from different databases and/or by using questionnaire surveys.
- Data cleaning: Data cleaning where one seeks to remove the noise, the inconsistent or erroneous.
- Data labelling: A process of labelling data by using certain criteria and assigning label or tags to the data.
- Data splitting: Splitting of the labeled data into portions for training, validation and test datasets.
- Model training: To develop and train machine learning algorithms with the help of labeled data.
- Model evaluation: Evaluation of the predictive ability of the models for fresh data.
- Model deployment: Shining light on the application of the trained model into applications.
Selecting a Data Labelling Company to Outsource
- Expertise: The labelling experience that the company has gained concerning different forms of data and previous labelling jobs it has executed.
- Quality control: Thus, the approaches used to preserve data integrity and production control.
- Scalability: The competence which the company has in dealing with big data and ensuring that most of the work is completed within the given time frame.
- Security: The data protection measures and the measures for privacy.
- Cost-effectiveness: Pricing – value got for the amount of money paid.
Infosearch with over eight years of data labelling experience has ensured the above mentioned points which are crucial to deliver high quality, data security and timely delivery of labelling services.
Importance of Data Quality in Data Labelling and Annotation Services
The quality of labeled data greatly influences the performance of machines as they learn. Labelling issues may result into biased or erroneous models. Thus, the goal would be selecting a top-notch data labelling company that has solid measures within quality assurance.
Machine learning and data labelling are two concepts that are used interchangeably in the modern world because of the close relationship between them.
It becomes crucial as data labelling is one of the key stages of developing machine learning. Perhaps it is not the only reason but it is definitely the basis upon which models are developed. It is critical to ensure that the labeled data that is being fed to models is of high quality to ensure the right results are obtained.
Infosearch is consistently delivering high quality labelling services to ALPR, Retail Analytics, Sports Analytics etc. industries.
Popular Searches:
data labelling companies, data labelling outsourcing, data labelling solutions, labelling data for machine learning
Data Labelling for Machine Learning
FAQs
Data labeling in the era of Generative AI In the era of Generative AI, data labeling transcends a simple tagging operation, and it assists in training AI models to be context-aware, intent-aware, tone-aware, accurate, and preference-aware. It is about organizing and authenticating training data in a manner that allows AI systems to produce meaningful, safe and contextual outputs.
The current data labelling facilitates activities like judging AI solutions, enhancing factual correctness, finding bias, and matching model results and user anticipations. Good labeled data is useful in ensuring generative models generate accurate and human-consistent results.
Data labeling is generally the process of labeling data by the application of simple tags or categories, as in object recognition in images, or categorizing text into stored categories. Data annotation is a larger process which can involve the provision of detailed metadata, contextual information or relationships in data.
Simply put, data labeling is a form of data annotation which concerns itself with classification whereas annotation may involve more sophisticated organization, such as segmentation, entity recognition or contextual labeling.
We are professionals in offering end-to-end data labelling services on a variety of data types, such as:
- Image and video classification (object detection, classification, segmentation)
- Image and video classification (object detection, classification, segmentation)
- Audio and speech labeling
- LLM response evaluation and conversational AI.
- Preparation of training data to generative AI models.
- Multi-modal data labeling
- Specialization labeling on specific industries.
Our services are tailored to fulfill the particular needs of AI, machine learning, and computer vision application.
RLHF is a machine learning method that creates AI models with human feedback and assessment to enhance them. The outputs of the model are evaluated by human reviewers, ranked, or their feedback to improve the results of a reward model is provided, which then directs the AI to produce improved results.
This procedure assists in aligning AI conduct to the anticipations of people, safety, and the quality of output in the applications of AI and large language models and generative AI frameworks.
Human-in-the-Loop (HITL) involves the use of automated tools together with human expertise in order to have a greater accuracy and reliability. Although automation is fast in labeling, human reviewers include contextual knowledge, corrections, and irregular and ambiguous cases.
This is a better method of improving the quality of data, minimizing bias, and better performing models because it integrates machine efficiency with human judgment and domain knowledge.
Infosearch offers dedicated workflows of multi-modal AI systems involving the combination of various data types like text, images, audio, and video. We make sure that there is constant labeling of various data sources so that AI models can know how modalities relate to each other.
To achieve precision, domain-trained experts, and smooth integration to train multi-modal models, we apply highly structured workflows, labeling tools, and positioning.
To train an effective AI model, many industries will need domain-specific data labeling and they include:
- Health and medical imaging.
- Robotics and self-driving cars.
- Retail and eCommerce
- Finance and banking
- The geospatial and mapping services.
- Security and surveillance
- Media and content platforms
Every industry demands specific labeling regulations, expertise in the industry, and quality assurance.
Yes. Scalability of high-volume AI projects makes us scale our data labeling operations due to our infrastructure, trained workforce and optimized workflows. We are efficient with large datasets, parallel processing, and can allocate resources flexibly with quality and consistency and turnaround time.
We provide a scalable service, which is efficient to accelerate the development and deployment of AI models in organizations.